- October 22, 2026
- Home
- Speed Over Perfection: Why Product Development Velocity Wins
Speed Over Perfection: Why Product Development Velocity Wins
Categories
Latest Post
- October 17, 2026
The £47K Technical Co-Founder Mistake: How Startups Can Protect a
- October 13, 2026
Why European Founders Resist AI Automation and How We Build

Speed Over Perfection: Why Product Development Velocity Wins
Competitors do not always win because they build better products. Often, they win because they reach users sooner, learn faster and make better decisions with real feedback.
That does not mean quality is unimportant. It means quality has to match the stage of the product.
At AppCatalyser, we see early-stage teams lose valuable time solving scale problems they may never face. They design complex infrastructure, debate long-term architecture and expand test coverage before the core product has proved useful to anyone.
The better approach is simple: build enough to test the main idea, protect the parts that carry real risk and improve the foundation when evidence justifies the investment.
What Is Product Development Velocity?
Product development velocity is the speed at which a team can turn an idea into a usable release, collect feedback and apply what it learns.
It is not the same as coding quickly. A team can write code fast and still move slowly if it builds unnecessary features, waits too long for approvals or creates a system that is difficult to change.
Real velocity comes from:
– A narrow and clearly defined product goal
– Fast decisions about what belongs in the first release
– Short build, test and feedback cycles
– Simple technology choices that suit the current stage
– Clear ownership and limited handovers
– The ability to correct or reverse a release quickly
Speed becomes useful when it produces learning. Shipping more work without learning anything is simply activity.
Why Does Speed Matter More Before Product-Market Fit?
Before product-market fit, the biggest uncertainty is not whether the system can support 100,000 users. It is whether the right users care enough to use or pay for the product.
Every week spent improving infrastructure before that question is answered uses budget without reducing the main business risk.
Consider two teams working on similar products.
Team A spends eight weeks preparing microservices, deployment environments and service boundaries. Team B launches a focused monolithic application in two weeks. During the next six weeks, Team B speaks with users, removes weak features and adjusts the main workflow.
When Team A finally launches, it may have cleaner architecture. Team B has something more valuable at that stage: evidence.
The first version does not need to predict the company’s entire future. It needs to make the next product decision clearer.
Speed Over Perfection Does Not Mean Shipping Carelessly
A speed-first approach is often misunderstood as permission to ignore engineering standards. That is not the goal.
Some areas should be protected from the beginning:
– User authentication and access control
– Payment processing
– Personal and sensitive data
– Critical business records
– Backup and recovery
– Basic error monitoring
– Legal and regulatory requirements
A visual imperfection can usually wait. A security vulnerability cannot. A report that needs manual formatting may be acceptable in an early release. Incorrect financial calculations are not.
The useful question is not, “Can we cut this corner?” It is, “What happens if this decision is wrong?”
If the answer involves lost data, exposed information, incorrect payments or serious customer harm, the work needs stronger safeguards. If the answer is that a small team will need to refactor a low-risk feature later, deferring it may be reasonable.
Where Early Product Teams Commonly Overbuild
Overengineering often begins with sensible intentions. Teams want to avoid future rework, so they prepare for scenarios that have not happened yet.
Infrastructure built for imagined scale
An early product may be prepared for millions of users before it has its first hundred. Complex container orchestration, multiple services and advanced observability can be valuable at scale, but they also introduce setup and maintenance work.
A simpler application with reliable deployment, backups and monitoring is often enough for an MVP. Infrastructure can evolve when real usage reveals the bottleneck.
Custom systems for solved problems
Authentication, email delivery, payments and file storage are important. They are not always where an early-stage team should spend its limited time.
Using a reliable managed service can reduce build time and operational risk. The dependency may cost more later, but switching costs should be compared with the value of reaching users sooner.
Features designed for every possible user
Trying to support every role, edge case and future market expands the first release quickly. The result is usually more screens, more testing and a less focused product.
The first version should support one valuable journey for a clearly defined user. Additional flexibility can be added when demand is visible.
Architecture shaped by assumptions
Teams sometimes separate services, introduce abstractions or design complex data models because they expect future requirements. If those assumptions change, the architecture can make the pivot harder rather than easier.
Simple systems are not automatically weak systems. In uncertain products, simplicity often preserves the ability to change direction.
How We Build MVPs for Speed Without Losing Control
At AppCatalyser, we use a focused development approach. The aim is to move quickly while keeping risks visible and manageable.
1. Define the decision the MVP must support
An MVP should answer a specific question. Will users complete the core workflow? Will they pay for the service? Does the process save enough time to justify adoption?
If the team cannot state what it needs to learn, the scope will keep growing.
2. Protect the essential user journey
We identify the shortest complete journey that delivers value. Everything needed for that journey stays. Features that do not help validate it are moved to a later phase.
This keeps the release useful without turning it into a full platform.
3. Use proven components where they make sense
Managed tools and established libraries can reduce weeks of work. We assess them based on security, integration effort, ownership, cost and the difficulty of replacing them later.
The fastest option is not always the first tool available. It is the option that solves the current need without creating an unreasonable future constraint.
4. Record deliberate shortcuts
Technical debt becomes dangerous when no one remembers why a decision was made.
We maintain a technical decision log that records:
– What was simplified or deferred
– Why the choice was reasonable
– What risk it creates
– When the decision should be reviewed
– Which metric or event should trigger an upgrade
For example, a simple background process may be sufficient until processing time or volume reaches a defined threshold. The team can then improve it based on evidence rather than prediction.
5. Make releases easy to observe and reverse
Early teams need confidence to ship. That confidence comes from visibility and recovery, not from trying to prevent every possible mistake.
Useful safeguards include:
– Error tracking
– Basic performance monitoring
– Automated deployment
– Tested backups
– Feature flags for higher-risk changes
– A clear rollback process
These controls help teams learn quickly without leaving customers exposed when something goes wrong.
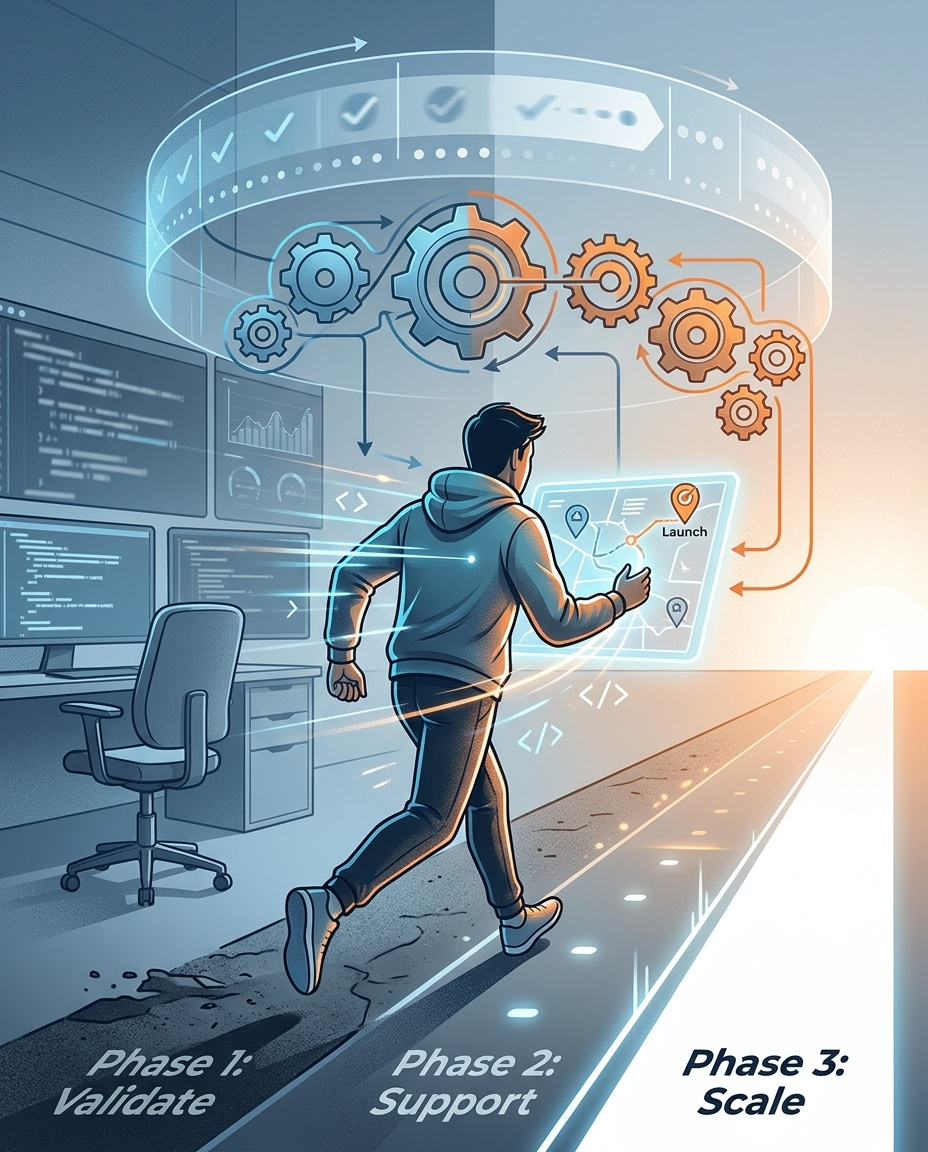
A Three-Phase Framework for Product Quality
The right engineering standard changes as the product gains evidence and users.
Phase 1: Validate the problem
The priority is to discover whether the product solves a real and valuable problem.
At this stage:
– Keep the scope narrow
– Use simple architecture
– Measure user behaviour
– Expect features to change
– Protect security and critical data
– Avoid building for hypothetical scale
The release should take weeks, not months. Some code may eventually be replaced, and that is acceptable if it produces useful learning.
Phase 2: Support early traction
This phase begins when the product shows meaningful demand through paying customers, repeat usage or strong engagement.
The focus now shifts towards reliability and repeatable delivery:
– Strengthen tests around critical workflows
– Improve deployment and rollback processes
– Address recurring performance problems
– Clarify important architectural boundaries
– Remove technical debt that slows frequent changes
– Improve documentation for a growing team
The goal is still not unlimited scale. It is to help the team keep shipping while customer expectations rise.
Phase 3: Scale proven demand
Once revenue and usage are consistent, decisions about scale become easier because the team has real data.
This is the stage to consider:
– Separating services with clear operational value
– Scaling databases and background processing
– Improving redundancy and recovery
– Expanding automated testing
– Strengthening observability
– Refining security and compliance controls
Technical debt that helped the team move early may now reduce velocity. Refactoring becomes worthwhile when it removes a demonstrated constraint.
When Should Technical Debt Be Addressed?
Not every untidy part of a codebase needs immediate attention. Technical debt should be prioritised when it affects users, revenue, security or the team’s ability to make changes.
Useful warning signs include:
– The same area causes repeated production issues
– A normal feature takes far longer than expected
– Developers avoid touching a critical part of the system
– Performance problems affect real users
– Security or compliance requirements cannot be met
– Releases require risky manual steps
– New team members cannot understand the system
Refactoring code that rarely changes and causes no business problem may feel productive, but it does not necessarily improve the product.
How to Find the Real Bottleneck Before Rebuilding
Teams often blame architecture when the actual problem is much smaller.
A slow application may be caused by one database query, a missing index, an inefficient external API call or an image-loading issue. Moving to microservices will not fix those problems.
Before planning a major rebuild:
– Measure where time and errors occur
– Identify the specific user impact
– Test the smallest practical fix
– Compare the result with the cost of architectural change
– Rebuild only when the current structure blocks necessary progress
Evidence should lead the architecture decision.
How AI-Assisted Development Changes Product Velocity
AI-assisted development tools can shorten research, coding, testing and documentation tasks. This makes it possible for smaller teams to explore ideas and release improvements more quickly.
The advantage does not come from generating more code. It comes from reducing the time between a product question and a real user response.
Human review still matters. AI-generated code can introduce insecure assumptions, incorrect dependencies or logic that appears convincing but does not fit the product. Teams need clear review standards for security, data handling and critical workflows.
Used well, AI can support product development velocity. Used without judgement, it can create technical debt faster.
How Should Product Development Velocity Be Measured?
Lines of code and number of releases do not show whether a team is moving in the right direction.
More useful measures include:
– Time from approved idea to user release
– Frequency of meaningful releases
– Time taken to recover from a release issue
– Percentage of users completing the core journey
– Learning gained from each release
– Time spent fixing repeated problems
– Lead time for high-priority changes
The aim is not constant activity. It is faster progress towards a product users value.
Final Thoughts
The market does not reward architecture in isolation. It rewards products that solve the right problem at the right time.
Early-stage teams should not choose between speed and responsible engineering. They should apply the right level of engineering to the risk in front of them.
Build the smallest useful release. Protect security, payments and critical data. Watch how users behave. Improve the foundation when evidence shows where investment is needed.
At AppCatalyser, we help founders move from idea to launch in weeks, not months. We define a focused scope, choose practical technology and build systems that are simple enough to change without ignoring the controls that matter.
If an MVP is taking too long because the team is debating future scale, we can help separate what the first release needs from what can wait.
Frequently Asked Questions
Is speed more important than code quality in MVP development?
Speed matters because an MVP needs user feedback, but core quality cannot be ignored. Security, payments, data integrity and the main user journey should be reliable from the first release. Lower-risk improvements can follow after validation.
How fast should an MVP be developed?
The timeline depends on scope and complexity, but a focused MVP should usually be measured in weeks rather than many months. If the schedule keeps expanding, the product may be trying to validate too many assumptions at once.
Is technical debt always bad?
No. Deliberate technical debt can help a team launch sooner when the risk is understood and documented. It becomes harmful when it creates repeated issues, blocks important features or affects security and customers.
When should a startup improve its architecture?
Architecture should be improved when real usage exposes a constraint, such as slow releases, performance problems, recurring incidents or difficult team collaboration. Evidence is a better trigger than predicted scale.
Can AI tools help teams build MVPs faster?
Yes. AI tools can support coding, testing and documentation, but their output still needs human review. They improve velocity when used inside a clear product and engineering process.